

Update model card for Spanish
Browse files
README.md
CHANGED
|
@@ -1,53 +1,92 @@
|
|
| 1 |
-
---
|
| 2 |
-
pipeline_tag: zero-shot-image-classification
|
| 3 |
-
language: spa
|
| 4 |
-
|
| 5 |
-
|
| 6 |
-
-
|
| 7 |
-
library_name: transformers
|
| 8 |
-
base_model: google/siglip2-large-patch16-512
|
| 9 |
-
base_model_relation: quantized
|
| 10 |
-
datasets:
|
| 11 |
-
-
|
| 12 |
-
---
|
| 13 |
-
|
| 14 |
-
# siglip2-large-patch16-512-spa-32768
|
| 15 |
-
|
| 16 |
-
This model
|
| 17 |
-
|
| 18 |
-
|
| 19 |
-
|
| 20 |
-
|
| 21 |
-
|
| 22 |
-
|
| 23 |
-
|
| 24 |
-
|
| 25 |
-
|
| 26 |
-
|
| 27 |
-
- **
|
| 28 |
-
- **
|
| 29 |
-
|
| 30 |
-
|
| 31 |
-
|
| 32 |
-
|
| 33 |
-
```python
|
| 34 |
-
from transformers import
|
| 35 |
-
|
| 36 |
-
|
| 37 |
-
|
| 38 |
-
|
| 39 |
-
|
| 40 |
-
|
| 41 |
-
|
| 42 |
-
|
| 43 |
-
|
| 44 |
-
|
| 45 |
-
|
| 46 |
-
|
| 47 |
-
|
| 48 |
-
#
|
| 49 |
-
|
| 50 |
-
|
| 51 |
-
|
| 52 |
-
|
| 53 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
pipeline_tag: zero-shot-image-classification
|
| 3 |
+
language: spa
|
| 4 |
+
license: apache-2.0
|
| 5 |
+
tags:
|
| 6 |
+
- trimmed
|
| 7 |
+
library_name: sentence-transformers
|
| 8 |
+
base_model: google/siglip2-large-patch16-512
|
| 9 |
+
base_model_relation: quantized
|
| 10 |
+
datasets:
|
| 11 |
+
- lbourdois/fineweb-2-trimming
|
| 12 |
+
---
|
| 13 |
+
|
| 14 |
+
# siglip2-large-patch16-512-spa-32768
|
| 15 |
+
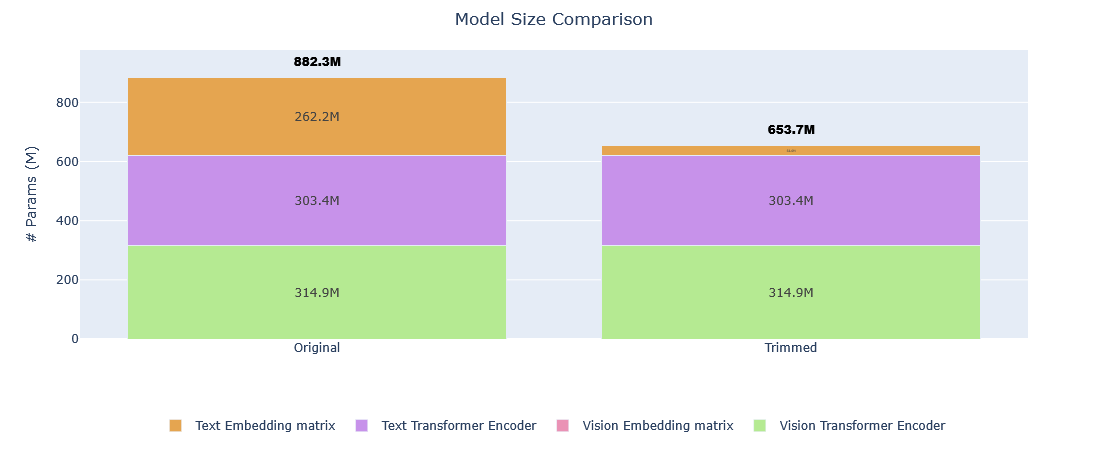
This model is a **25.91%** smaller version of [google/siglip2-large-patch16-512](https://huggingface.co/google/siglip2-large-patch16-512) optimized for **Spanish** language via vocabulary size reduction using the [trimming](https://huggingface.co/blog/lbourdois/introduction-to-trimming) method.
|
| 16 |
+
This trimmed model should perform similarly to the original model with only 32,768 tokens and a much smaller memory footprint. However, it may not perform well for other languages as tokens not commonly used in the selected languages were removed from the vocabulary.
|
| 17 |
+
|
| 18 |
+
## Model Statistics
|
| 19 |
+
| Metric | Original | Trimmed | Reduction |
|
| 20 |
+
|--------|----------|---------|-----------|
|
| 21 |
+
| **Vocabulary size** | 256,000 tokens | 32,768 tokens | **87.20%** |
|
| 22 |
+
| **Model size** | 882,313,218 params | 653,723,650 params | **25.91%** |
|
| 23 |
+
|
| 24 |
+
|
| 25 |
+
|
| 26 |
+
## Mining Dataset Statistics
|
| 27 |
+
- **Number of texts used for mining**: 200,000 texts
|
| 28 |
+
- **Dataset**: [lbourdois/fineweb-2-trimming](https://huggingface.co/datasets/lbourdois/fineweb-2-trimming)
|
| 29 |
+
|
| 30 |
+
## Usage
|
| 31 |
+
|
| 32 |
+
#### Transformers (zero-shot image classification)
|
| 33 |
+
```python
|
| 34 |
+
from transformers import pipeline
|
| 35 |
+
|
| 36 |
+
# load pipeline
|
| 37 |
+
image_classifier = pipeline(model="alphaedge-ai/siglip2-large-patch16-512-spa-32768", task="zero-shot-image-classification")
|
| 38 |
+
|
| 39 |
+
# load image and candidate labels
|
| 40 |
+
image = "http://images.cocodataset.org/val2017/000000039769.jpg"
|
| 41 |
+
candidate_labels = ["Potential label 1 in Spanish", "Potential label 2 in Spanish", "Potential label 3 in Spanish", "Potential label 4 in Spanish"]
|
| 42 |
+
|
| 43 |
+
# run inference
|
| 44 |
+
outputs = image_classifier(image, candidate_labels)
|
| 45 |
+
print(outputs)
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
#### Sentence-transformers (texts-images similarity)
|
| 49 |
+
```python
|
| 50 |
+
from sentence_transformers import SentenceTransformer
|
| 51 |
+
|
| 52 |
+
model = SentenceTransformer("alphaedge-ai/siglip2-large-patch16-512-spa-32768")
|
| 53 |
+
|
| 54 |
+
images = [
|
| 55 |
+
"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/car.jpg",
|
| 56 |
+
"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg",
|
| 57 |
+
"https://huggingface.co/datasets/huggingface/cats-image/resolve/main/cats_image.jpeg"
|
| 58 |
+
]
|
| 59 |
+
texts = ["Text 1 in Spanish", "Text 2 in Spanish", "Text 3 in Spanish", "Text 4 in Spanish"]
|
| 60 |
+
|
| 61 |
+
image_embeddings = model.encode(images)
|
| 62 |
+
text_embeddings = model.encode(texts)
|
| 63 |
+
print(image_embeddings.shape, text_embeddings.shape)
|
| 64 |
+
|
| 65 |
+
similarities = model.similarity(image_embeddings, text_embeddings)
|
| 66 |
+
print(similarities)
|
| 67 |
+
```
|
| 68 |
+
|
| 69 |
+
## Citations
|
| 70 |
+
|
| 71 |
+
#### SigLIP 2
|
| 72 |
+
```
|
| 73 |
+
@misc{tschannen2025siglip2multilingualvisionlanguage,
|
| 74 |
+
title={SigLIP 2: Multilingual Vision-Language Encoders with Improved Semantic Understanding, Localization, and Dense Features},
|
| 75 |
+
author={Michael Tschannen and Alexey Gritsenko and Xiao Wang and Muhammad Ferjad Naeem and Ibrahim Alabdulmohsin and Nikhil Parthasarathy and Talfan Evans and Lucas Beyer and Ye Xia and Basil Mustafa and Olivier Hénaff and Jeremiah Harmsen and Andreas Steiner and Xiaohua Zhai},
|
| 76 |
+
year={2025},
|
| 77 |
+
eprint={2502.14786},
|
| 78 |
+
archivePrefix={arXiv},
|
| 79 |
+
primaryClass={cs.CV},
|
| 80 |
+
url={https://arxiv.org/abs/2502.14786},
|
| 81 |
+
}
|
| 82 |
+
```
|
| 83 |
+
|
| 84 |
+
#### Trimming blog post
|
| 85 |
+
```
|
| 86 |
+
@misc{hf_blogpost_trimming,
|
| 87 |
+
title={Introduction to Trimming},
|
| 88 |
+
author={Loïck BOURDOIS and Tom AARSEN and Bram VANROY and Christopher AKIKI and Woojun JUNG and Manuel ROMERO and Prithiv SAKTHI},
|
| 89 |
+
year={2026},
|
| 90 |
+
url={https://huggingface.co/blog/lbourdois/introduction-to-trimming},
|
| 91 |
+
}
|
| 92 |
+
```
|